ModelGenius follows a statistically rigorous, repeatable process to validate your real traffic against lower-cost models and returns a defensible switch recommendation for every workload.
Point us at your AI traffic
Start by sharing a representative sample of your production LLM traffic. There is no hard rule, but one to two weeks usually gives us enough volume to understand your workflows, endpoint patterns, model usage, and cost drivers.
To make logging easy, you can use the ModelGenius trace logger, adapt it to your environment, use OpenRouter broadcast mode, or write your own logger against our specification.
Internal AI rarely flows through one front door. Coding agents, CI pipelines, review bots, and home-grown tools each record their traffic differently — so this step is built around your environment, not ours.
We provide adapters for common setups and build against yours where it’s bespoke, working with your platform team to capture one to two weeks of representative traffic. From there, the process is identical.
A JSONL of your production calls — one to two weeks of representative traffic is usually sufficient.
Discover your savings opportunities
Once your traces are connected, ModelGenius screens your traffic to find the workflows and task types with the highest switching potential.
We rank them by estimated annual savings, drawing on a proprietary analysis of call complexity, task characteristics, traffic volume, model usage, and current spend. The result is a prioritized list, so you can start with the biggest opportunities first.
The cheapest model on paper is not always the cheapest model in production. At ModelGenius, we measure outcomes — total cost to complete the task, never dollars-per-token price in isolation.
Generate comprehension assessments for reading passages by grade and genre.
Prove what’s safe — on your own traffic
We build the test plan for you: a quality benchmark derived from your own traffic, the candidate models worth testing, the evaluation criteria, and the failure modes that matter most. Review it, ask questions, and request changes. Nothing runs until you’ve had a chance to approve it.
Then we replay your traffic against your current model and the approved candidates. Follow the results as they come in—which models are still in contention, which have been ruled out, and why. You can pause or stop the run at any time.
Ask ModelGenius questions throughout: “Why is this model leading?” “Where is it falling short?” “What does this failure mean?” Get plain-English answers so you can understand the tradeoffs as the evidence builds.
A switch decision you can stand behind
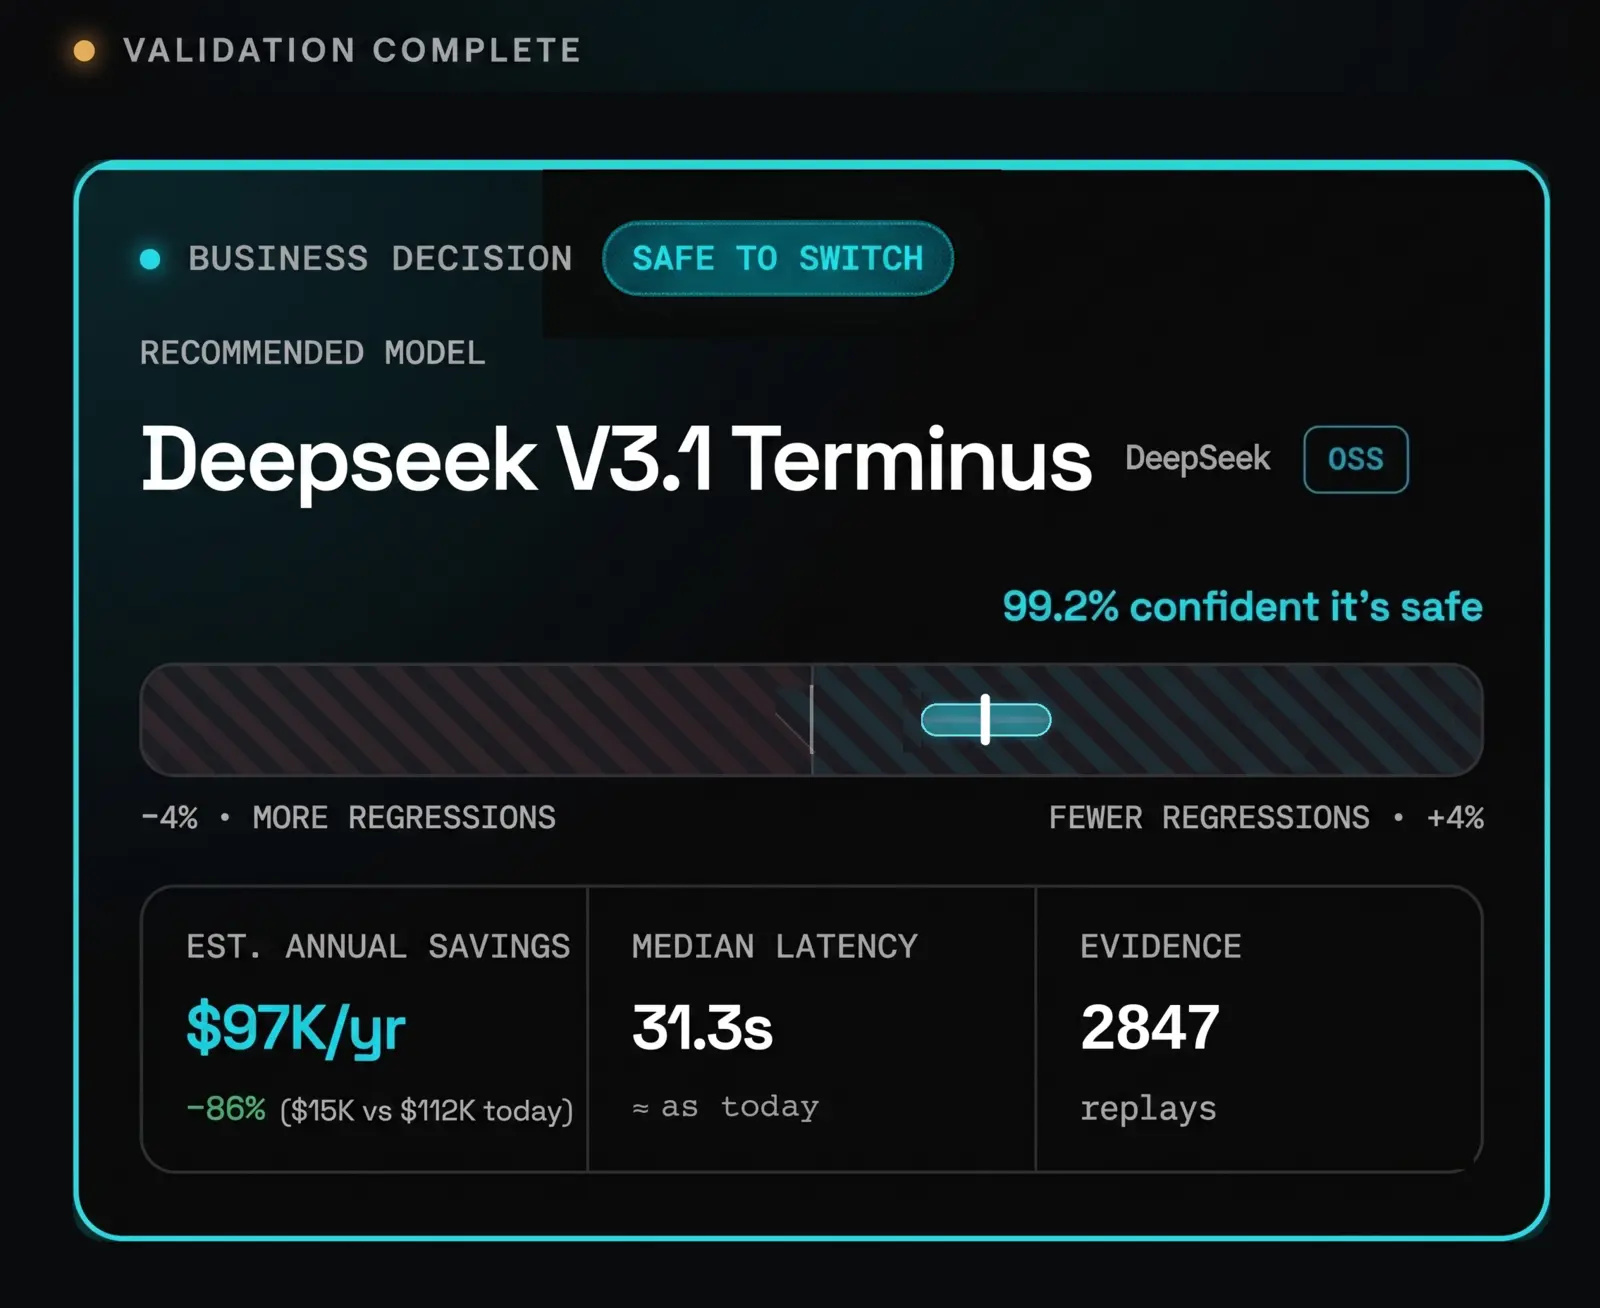
For every workload, validation delivers a clear recommendation: whether to switch, which model to choose, and how much you could save—with a confidence score grounded in the results.
The evidence is one conversation away. Ask how candidates compare on cost, quality, or latency, explore regressions and failure modes, or dig into individual trials—all in plain English.
Stay on the right model as the market and your AI workloads move
The right model today may not be the right model next month. ModelGenius keeps monitoring new model releases, pricing changes, and provider updates against the profile of your validated workflows. When a new candidate becomes worth testing, we flag it so you do not have to manually track the model market.
We compare baseline and candidate outputs across production samples using a carefully derived quality benchmark. Each validation run defines success criteria up front, prioritizes failure types, tracks confidence as the sample grows, and pauses early when high-priority regressions appear.